A blog about synapses, synaptic plasticity and in particular Hebbian synapses that 'fire together, wire together". It also serves as the course blog for "From Synapse to Circuit; Self-Organization of the Brain", an advanced undergraduate class, BIO 338, I teach every fall at Stony Brook University. Lecture Notes are available at syndar.org, but the version there is rather out of date.
For example in an already classic paper (Matsuzaki, M., Honkura, N., Ellis-Davies, G. & Kasai, H.Structural basis of long-term potentiation in single dendritic spines. Nature429, 761–766 (2004)., he showed that induction of LTP at single synapses (by pairing punctate glutamate application with postsynaptic depolarization) triggers changes in strength and spine head volume, which is confined to that synapse and does not spread to neighboring synapses:
Top graph shows changes in strength and volume at a hippocampal synapse where ltp is induced, with no change at neighbors. Ignore bottom graph.
He concluded: "Our results thus indicate that spines individually follow Hebb's postulate for learning."
In the recent study (Nature Volume 525, Issue 7569, 17 September 2015, Pages 333-338), he looked at synapses in the motor neocortex during and after learning of a motor task (the ability to cling to a rotating rod). Using special molecular markers he was able to identify a set of synapses on the dendrites of a pyramidal cell that became strengthened following task learning. Then, crucially, he was able to shrink those synapses back to their original size, and show that this selectively erased learning of this task, but not others. This strongly suggests that strengthening of these synapses (presumably as a result of Hebbian ltp occurring during learning) underlies the relevant learning.
Of course we do not know which circuits these synapses belong to, or exactly what role they play in learning the task.
Paul Modrich elucidated mismatch repair, the final step in ensuring accurate DNA replication. Recently we have come to recognize (almost) miraculous replication accuracy as the driver of evolution, rather than the anyway inevitable mistakes (i.e. mutation). As we discussed the main step underlying accuracy is however "proofreading", a concept proposed independently and simultaneously by an earlier Chemistry Nobelist, John Hopfield, and the now almost unknown Jacques Ninio.
Similar extreme accuracy in the strengthening of synapses could underlie learning, especially in the neocortex, where a type of neural proofreading might occur, generating what we loosely call "mind" (see syndar.org). We will not be discussing this rather speculative "Hebbian proofreading" concept in BIO 338, but if anyone is interested please contact me. However we will be discussing related aspect of synapses and neocortical operation. Congratulations to all 3 winners! There are very surprising and interesting implications of proofreading for the way DNA is replicated. As summarized in the Alberts textbook:- "The need for accuracy probably explains why DNA replication occurs only in the 5′-to-3′ direction. If there were a DNA polymerase that added deoxyribonucleoside triphosphates in the 3′-to-5′ direction, the growing 5′-chain end, rather than the incoming mononucleotide, would carry the activating triphosphate. In this case, the mistakes in polymerization could not be simply hydrolyzed away, because the bare 5′-chain end thus created would immediately terminate DNA synthesis (Figure 5-11). It is therefore much easier to correct a mismatchedbase that has just been added to the 3′ end than one that has just been added to the 5′ end of a DNA chain. Although the mechanism for DNA replication (see Figure 5-8) seems at first sight much more complex than the incorrect mechanism depicted earlier in Figure 5-7, it is much more accurate because all DNA synthesis occurs in the 5′-to-3′ direction.
Figure 5-11An explanation for the 5′-to-3′ direction of DNA chain growth
Growth in the 5′-to-3′ direction, shown on the right, allows the chain to continue to be elongated when a mistake in polymerization has been removed by exonucleolytic proofreading (see Figure 5-9). In contrast, exonucleolytic proofreading in the hypothetical 3′-to-5′ polymerization scheme, shown on the left, would block further chain elongation. For convenience, only the primer strand of the DNAdouble helix is shown.
NCBI Bookshelf. A service of the National Library of Medicine, National Institutes of Health.
Thus proofreading requires unidirectional strand copying, which in turn explains why replication is done using an otherwise complex and cumbersome "replication fork" machinery for the lagging strand. Of course evolving this macxhinery was an unlikely, difficult and individual-fitness lowering process (rather like sex), but it was necessary for all life as we know it to emerge billions of years ago.
I mentioned in class that transmitter release is mediated by 2 key molecules (or more exactly, types of molecule), the SNARES and synaptotagmin. SNARES are protein that bring the vesicle membrane and the presynaptic plasma membrane together at the active zone (where release occurs). The new paper ( Nature, 525, 62–67, 03 September 2015) describes an X-ray crystalographic study of the interface between the calcium-detecting molecule synaptotagmin (on the vesicle membrane) and the SNARES, which are anchored in both vesicle and plasma membranes, and come together in the narrow space between them to form a "helix bundle". When calcium binds to the synaptotagmin it, via its interface with the SNARES, triggers a contraction of the helix bundle pulling the 2 membranes together and then dragging them so they actually fuse. Here's the key diagram from the paper (which the Nature robot might censor, but you can also look at online at the University library); look particularly at parts c,d and e.
Of course one always knew, since Katz's seminal discovery of the role of calcium in transmitter release, that the underlying molecular machinery would eventually be mapped out, but it's still very satisfying to see all the details falling into place. Sudhof, one of the authors of the new paper, had already received the 2013 Nobel Prize for his work (with Rothman and Scheckman) for his work on the molecular mechanism of exocytosis.
Here's the comment I just posted on my Facebook page (which should not be directly accessible to you):
She's a good scientist, but misleads when she says that studying the worm brain might help understand the human brain. It might, but already it's clear that it probably won't answer any of the important questions, like how does the cortex work? Essentially she's looking for her keys where the light is, not in the dark place she dropped them. Of course there may be interesting objects under the lamp-post - even a million dollars which would buy a good locksmith, but it's rather unlikely. To understand the human brain you have to study the cortex directly: try to find the out what the circuits are and what they do, and above all whether there are general principles that underlie the observed variations which specifically explain the features we are most interested in (eg intelligence). Of course evolution does manifest a type of intelligence, and there may be interesting deep connections with neural intelligence.
The above videos should be helpful in understanding the structure and function of the basic type of potassium channel, the "inward rectifier". My lecture and Notes describe the basic features of selective permeation, especially the narrowest part of the open pore the "selectivity filter". This is lined with 20 (5X4) carbonyl groups, all pointing to the interior. These are part of the backbone of the polypeptides, and the corresponding amino acid side chains point outward and interact with the rest of the protein, so the carbonyls are held rigidly, and cannot move inward to better contact sodium ions. Therefore these ions cannot lower their energy enough to compensate for that gained by losing H20 "hydration" molecules as they squeeze into the narrow pore. But K+ ions can lower their energy and enter the narrow part of the pore, and then easily move from site to site (e.g s1 to s2 or s3 to s2), depending on whether adjacent sites are already occupied by a K ion. Because the narrow part of the pore (the "filter") always has 2 ions (otherwise the complex structure collapses, eg at very low K cocentration) the only movements we need consider are between the 2 possible states 1,3 or 2,4. Both can occur, but the relative numbers depend on factors such as K concentration on both sides of the membrane, Vm and the chemical energies of the ions in different states. While I diagrammed a simplified "chemical energy" diagram, which showed only equally low energy wells, with the ion pair are located at the lowest energy positions, of course the ions are moving and the total chemical energy depends at any time depends on state and position. It's the complete energy profile for all possible combinations of state (though to a good approximation only movements between the 1,3 and 2/4 states are important and position that actually determine the movements of ions and thus the unidirectional and net potassium currents (more about this in a later lecture).
Crucially the membrane potential affects the energies at all positions. A reasonable approximation is to assume the field is constant at all positions (this "constant field" assumption is used in deriving the GHK membrane equation referred to in the lecture on membrane potential), i.e. that the voltage changes linearly with position (though perhaps most of the potential drop occurs along the narrow filter, so we would first consider the situation at zero Vm, then at other Vms. (I will post diagrams for this)
Notice one crucial point: whatever the current at various Vms and K external/internal concentrations we know that the net K current at the K Nernst potential must be zero, and our quantative analysis must yield this result.
THe main point of this discussion that embodying our recent understanding of molecular structural details can take us far beyond the simple pictures we used before (either Ohm's law or electrodiffusion across a uniform membrane as in the GHK picture). However it can get complicated , and these more detailed models don't really affect the basic conclusions we reached previously: qualitaively Ik = Gk(Vm-Ek). They do offer a more complete picture of ion channel function, and you should know the gist of the ideas involved.
SUMMARY: the movement of K ions through the selectivity filter can be modeled as cycling between 1,3 and 2/4 states. Inic current occurs when there are move cycles in 1 direction than the other. When the pore moves form the first state to the second, an ion has moved inward, and vice versa. If the concentration difference on either side is zero, and Vm is too, then clearly there cannot be net cycling either way. If Kout/Kin is > 1, with Vm = 0, there will be net inward cycling; if K out/Kin = 1 bit Vm is < 0, there will also be net inward cycling. If Vm = Ek (the Nernst potential) there is no net cycling though neither Vm = 0 nor Ko/Ki = 1. In general knowing the energy profile for various pore occupancy states allows one to calculate Ik under any conditions.
Evelyn Witkin just won the Lasker Prize (often a prelude the Nobel) for her pioneering work on DNA repair . As I explained in my lecture, the polymerase that quickly repairs damaged DNA (eg by UV light) is a "sloppier copier" - it has to work very quickly to copy the short error-free (parental) strand, after removing the stretch that contains the damage. To do this fast, it dispenses with proofreading, which of course greatly increases the mutation rate, and can lead to cancer - a disease that's closely related to the Eigen "error catastrophe".
see http://bcove.me/a7l91kqj for a nice video on mismatch repair (which is repair of replicative errors).
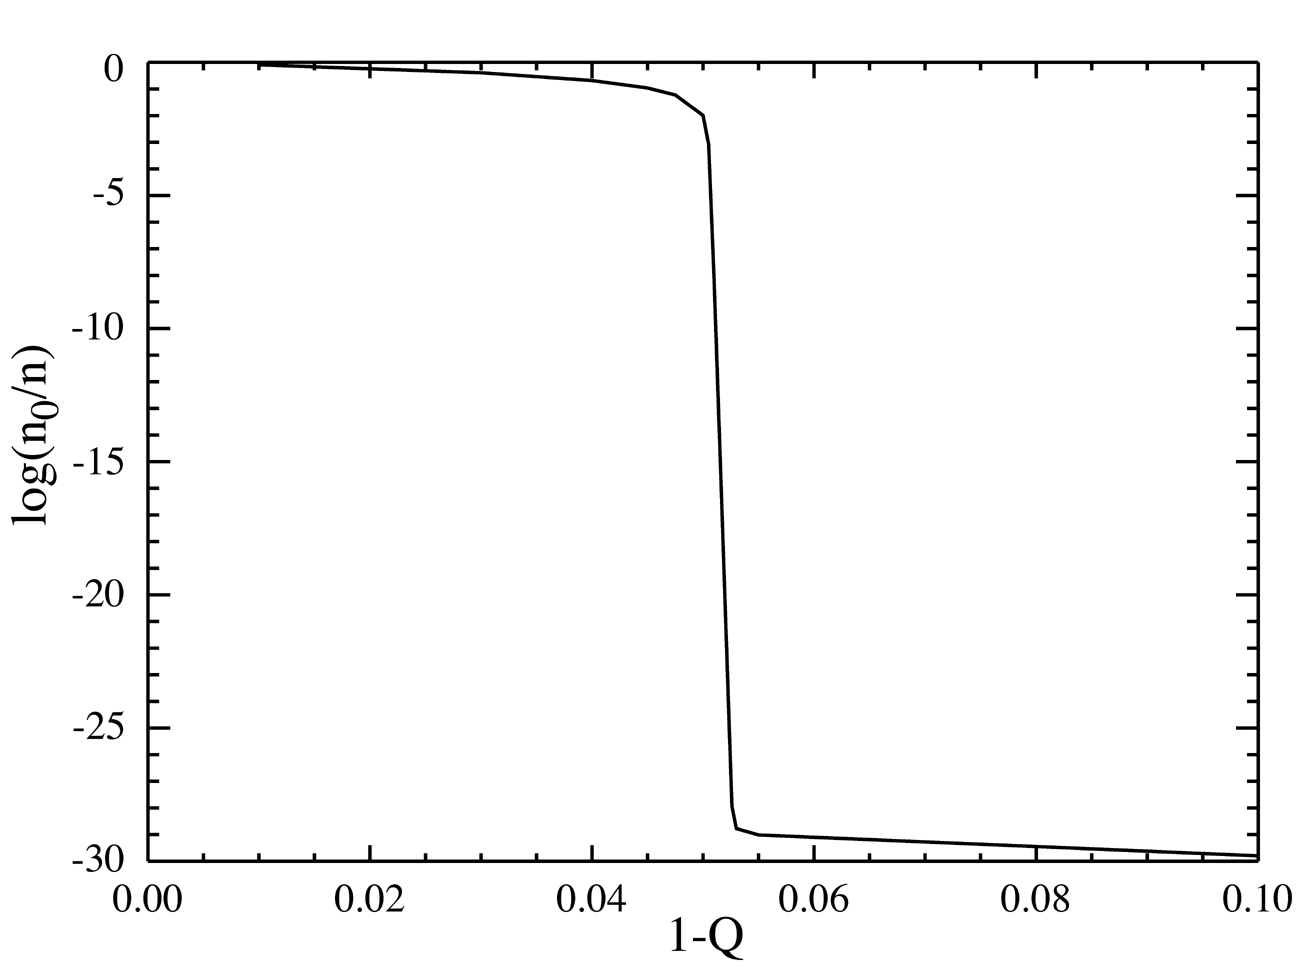
The population of the master sequence as a fraction of the total population (n) as a function of overall mutation rate (1-Q). The total number of digits per sequence is L=100, and the master sequence has a selective advantage of a=1.05. The "phase transition" is seen to occur at roughly 1-Q=0.05. From https://en.wikipedia.org/wiki/Error_threshold_(evolution) NOTE: the ordinate (Y-axis) is on a log scale, so the almost all-or none change in the concentration of the master is by a factor around 10^28 (ten to the twenty eight, a million times greater than Avogadro's number. Here is part of the student's interpretation of my lecture on Eigen's model, and my response, in bold. More to follow....
"The Eigen model of molecular evolution allows us to make a connection between darwinian evolution and the origins of DNA/ RNA replication. Eigen's model works on the basis that in our universes early history, RNA were able to fold and function as catalysts for Polypeptide replication before DNA came into the picture. When DNA developed, the process changed slightly, including the creation of complimentary strands before the identical strand is produced. "
Not quite right. Eigen's model does not explicitly aim to model conditions on the early earth, nor to describe the special case of RNA replication. Indeed at the time the model was first developed (1970), the catalytic abiilities of RNA were not yet recognized. Eigen's model had a more general aim: to describe quantitatively a simplified and generalized model of polynucleotide (or indeed heteropolymer) replication. The first core feature is sequence copying - that the precise linear sequence of n monomers in a polymer made up of at least 2 different monomers (for convenience represented as 0 or 1) depends in a 1-to-1, 0 to 0 fashion on the precise linear sequence of another "template" sequence. All other specifics are left out. As I explained, we must consider the relative concentration of all possible 2^n possible sequences when each sequence is growing exponentially at different rates phi but also "killed" (eg by simple dilution) with equal probability (because every so often half the solution is thrown away, so as to keep the total number of molecules constant despite the ongoing replication.
So 2 key features of the model are sequence-specific replication and competition for resources (i.e. hi-energy nucleotides). The third crucial feature is the possibility of mistakes in copying individual monomers (eg bases) despite the high specificity of e.g Crick-Watson base pairing. This is a minimal model of Darwinian evolution at the molecular (not organismal) level. Eigen suspected, and was able to prove (both mathematically and experimentally - a nice combination) that if the error rate e exceeded a critical value approximately equal to 1/n, that Darwinian natural selection would stop. Or, applied to the Origin of Life problem, that since on the early earth replication (i.e. template-dependent copying) was probably rather inaccurate, Darwinian evolution could not start until the relevant catalyst (whatever it was) became accurate enough that e < 1/n. The whole point is that at least in the model there is a sharp dividing line (analogous to a phase transition) between purely chemical processes (eg low-accuracy copying) and Darwinian evolution (= Life) at a critical error rate ~ 1/n.
Note that while the model explicitly considers only sequences of fixed length n exactly the same outcome would be observed in a model with variable length n (for example, in the likely case that shorter sequences were more likely than longer ones). The model throws out all the interesting but basically irrelevant details to focus on the essence of the problem: point mutation.